Yixuan Ren
I am a Research Scientist at Luma AI, working on multimodal foundation training for robotics and media creation. I also work on coding/agentic policy for robot manipulation.
I obtained my Ph.D. in Computer Science at the University of Maryland, College Park, advised by Prof. Abhinav Shrivastava. I also received my M.S. degree here. Prior to that, I received my B.E. degree from Tsinghua University.
- 2025
 Meta GenAI/MSL Mannat Singh, Saketh Rambhatla, Andrew Brown, Arun Mallya
- 2023
 Adobe Research Yang Zhou, Difan Liu, Jimei Yang, Jing Shi, Feng Liu
- 2022 Adobe Research Jing Shi, Zhifei Zhang, Yifei Fan, Zhe Lin
- 2021
 ByteDance Xiao Yang, Bingchen Liu, Yizhe Zhu
Publications
* equal contribution † project lead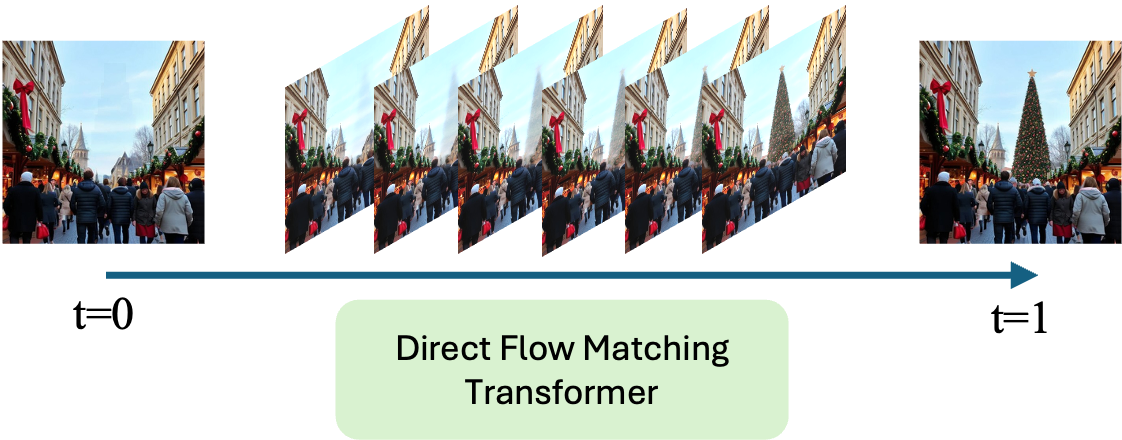
Flow directly from source to target images for efficient inversion-free instructional image editing.
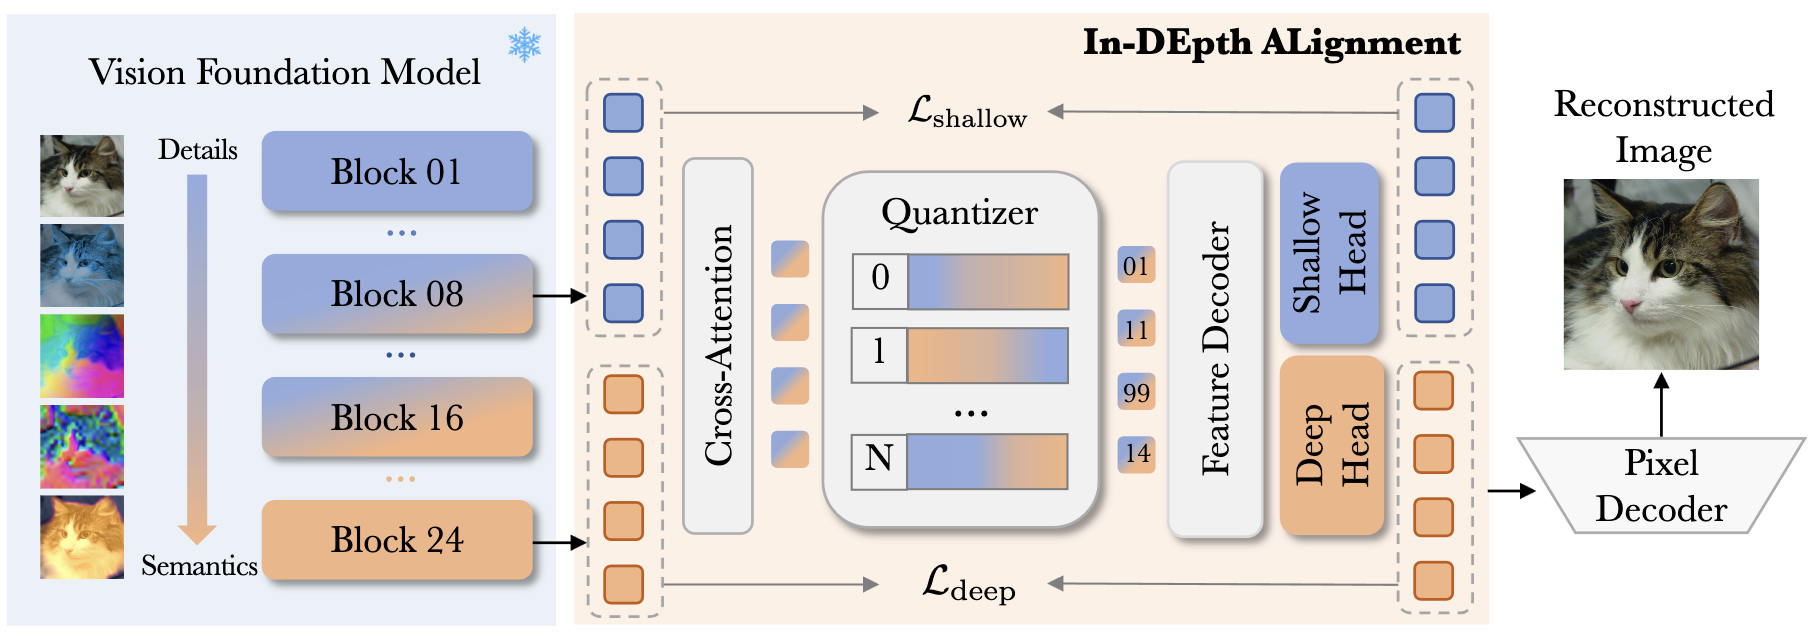
A discrete representation autoencoder with hierarchical vision alignment for generative image tokenization.
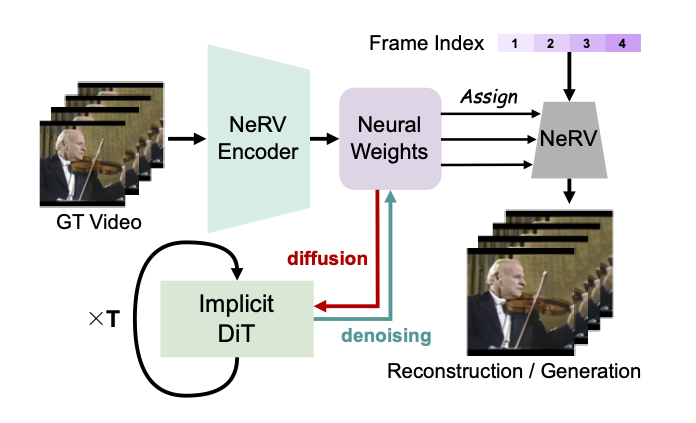
Generate network weights via a diffusion model, which parameterize an implicit neural representation and self-decode to synthesize a video.
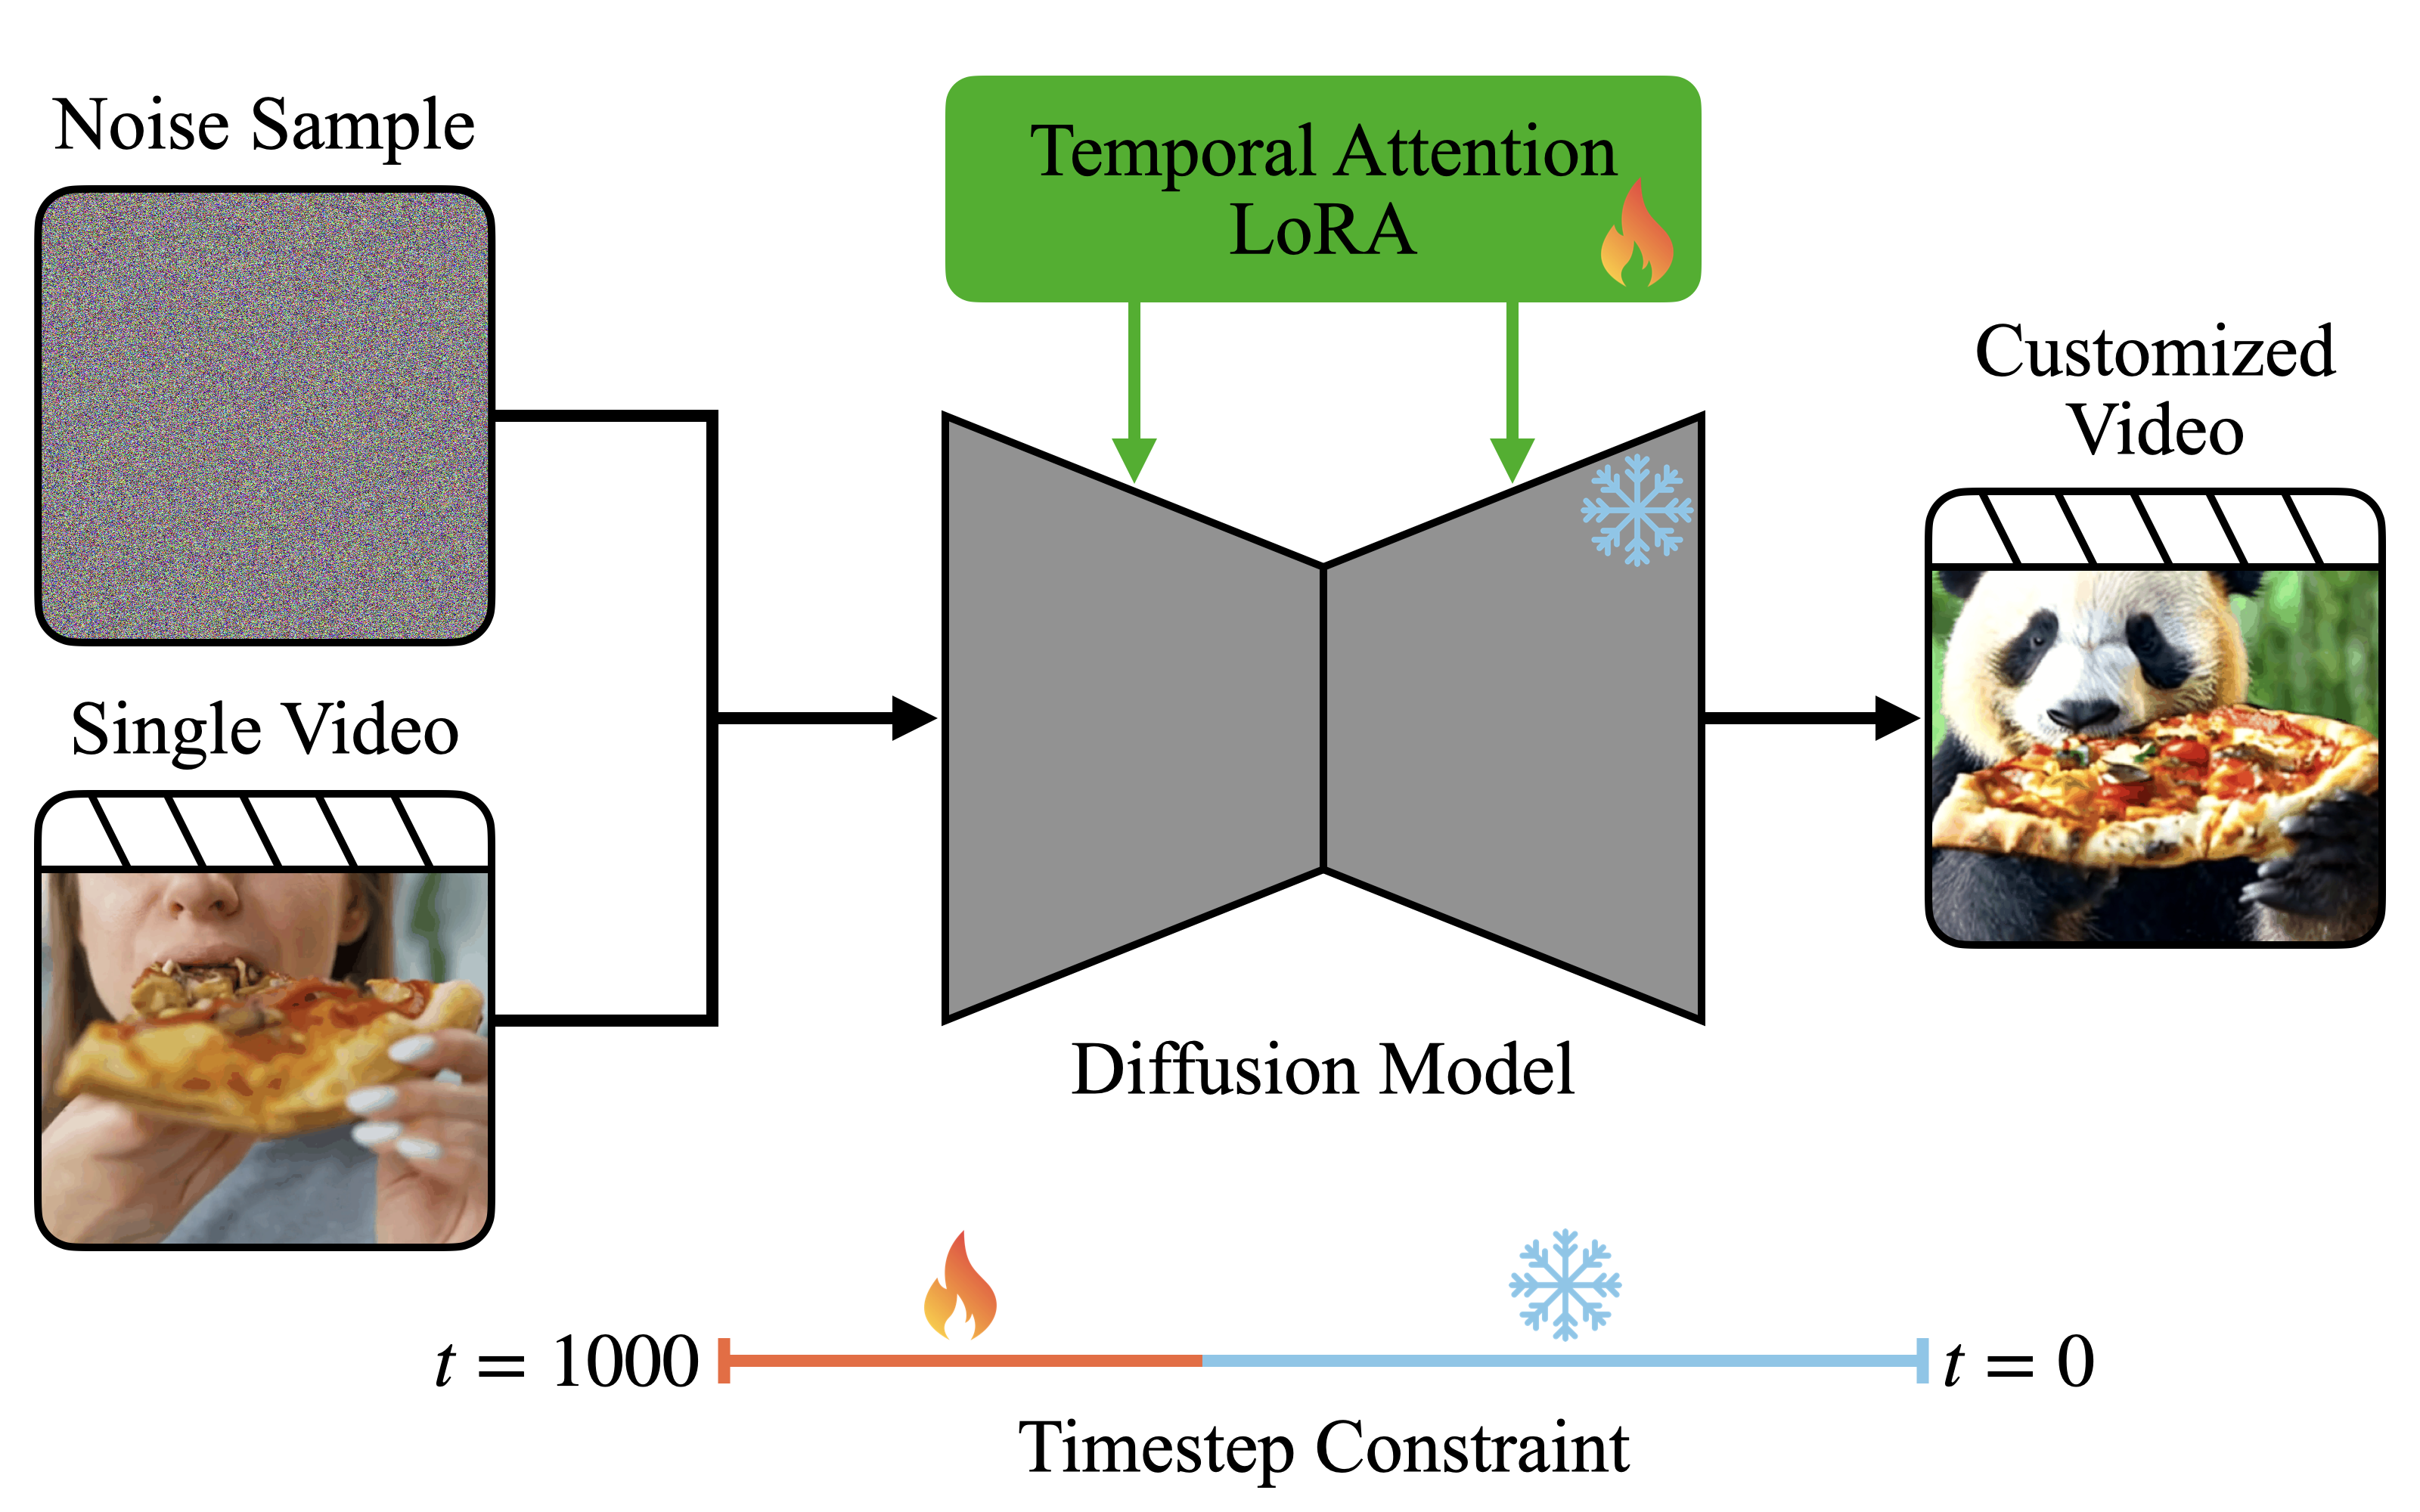
Single-stage one-shot video motion customization via constraining within temporal-dominant early denoising timesteps.
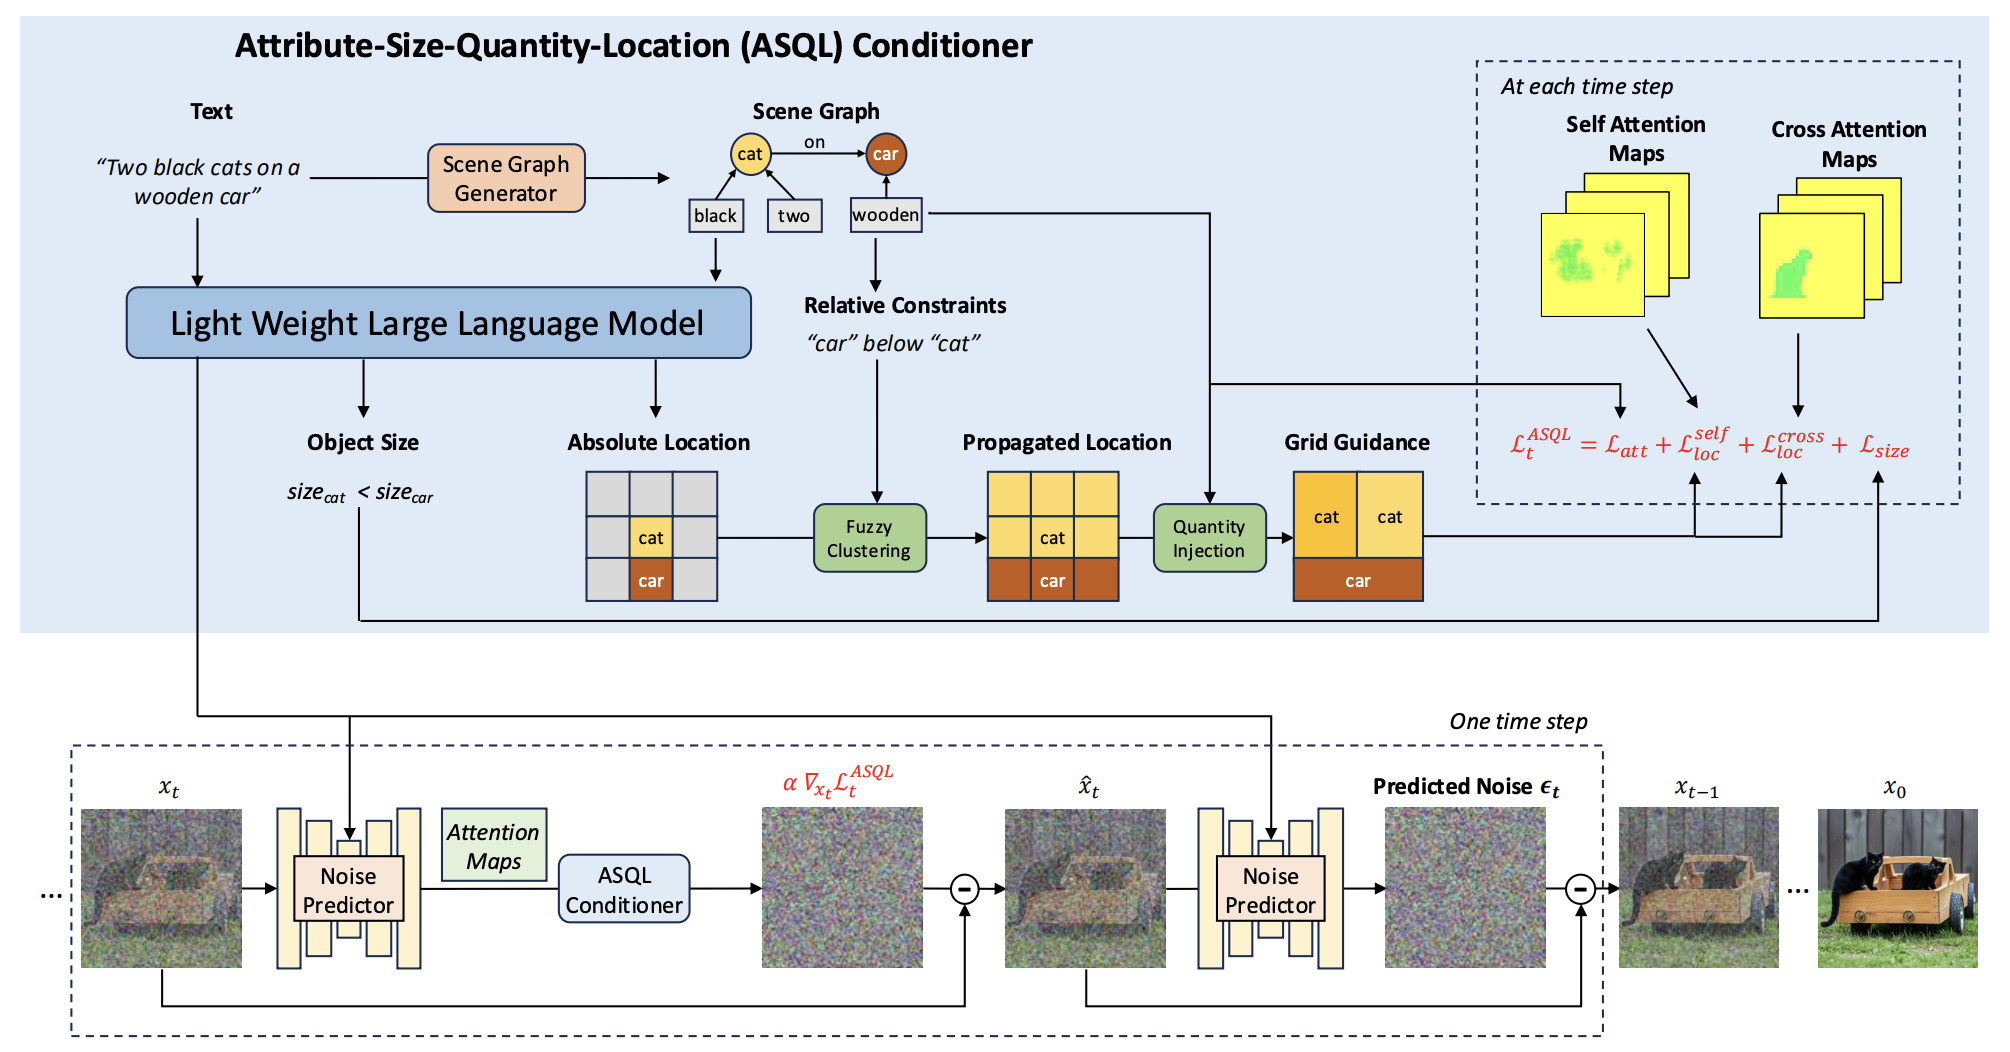
A zero-shot, scene graph-based conditioning mechanism for compositional text-to-image generation with soft visual guidance.
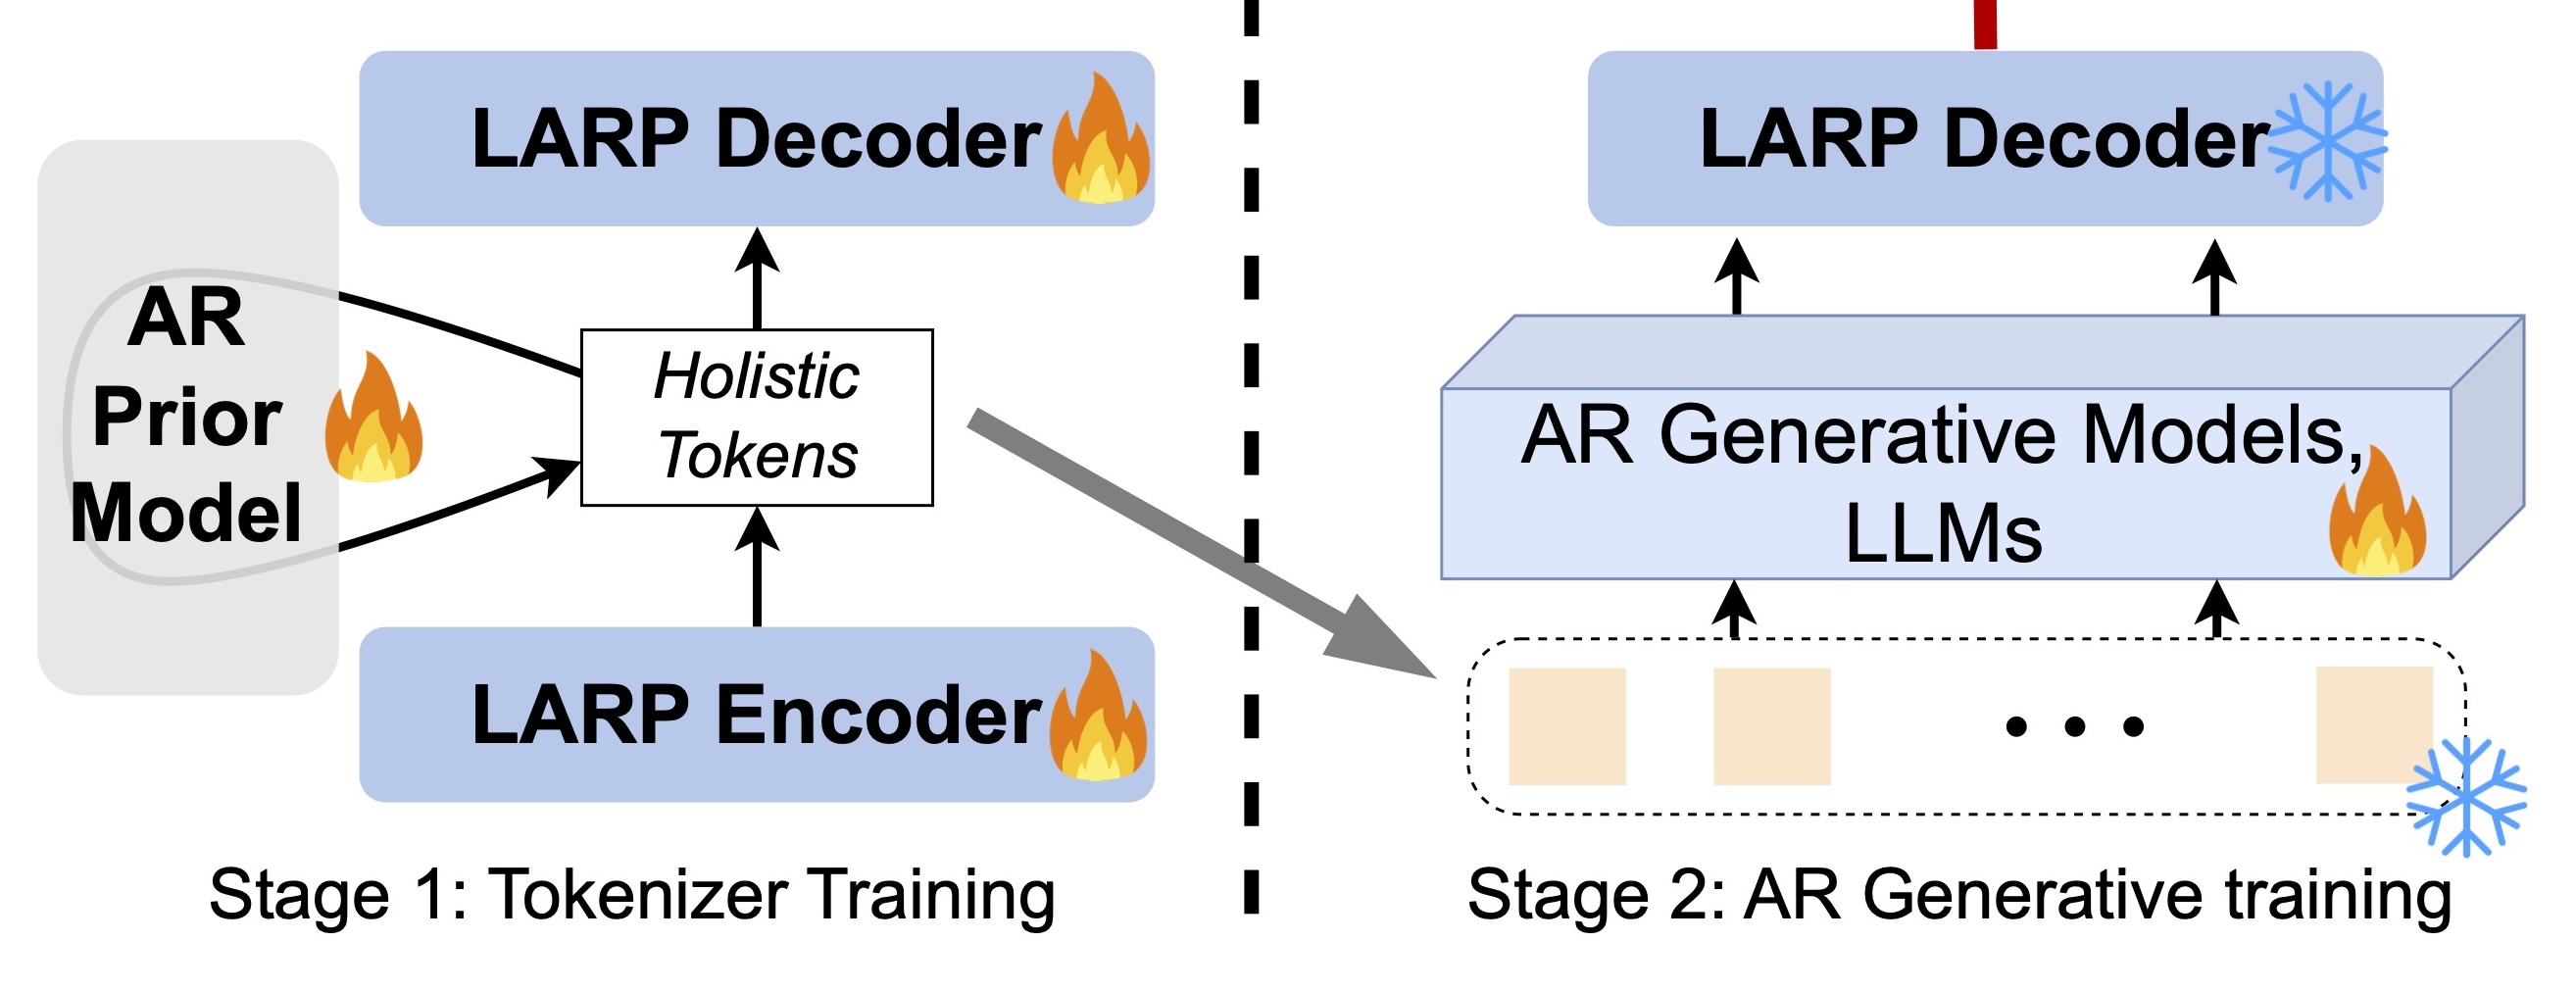
A holistic video tokenizer that integrates a light weight autoregressive transformer to align the latent space with AR generative models.
Customize pre-trained video diffusion models from a single reference video and adapt its motion to new subjects and scenes with temporal diversity.
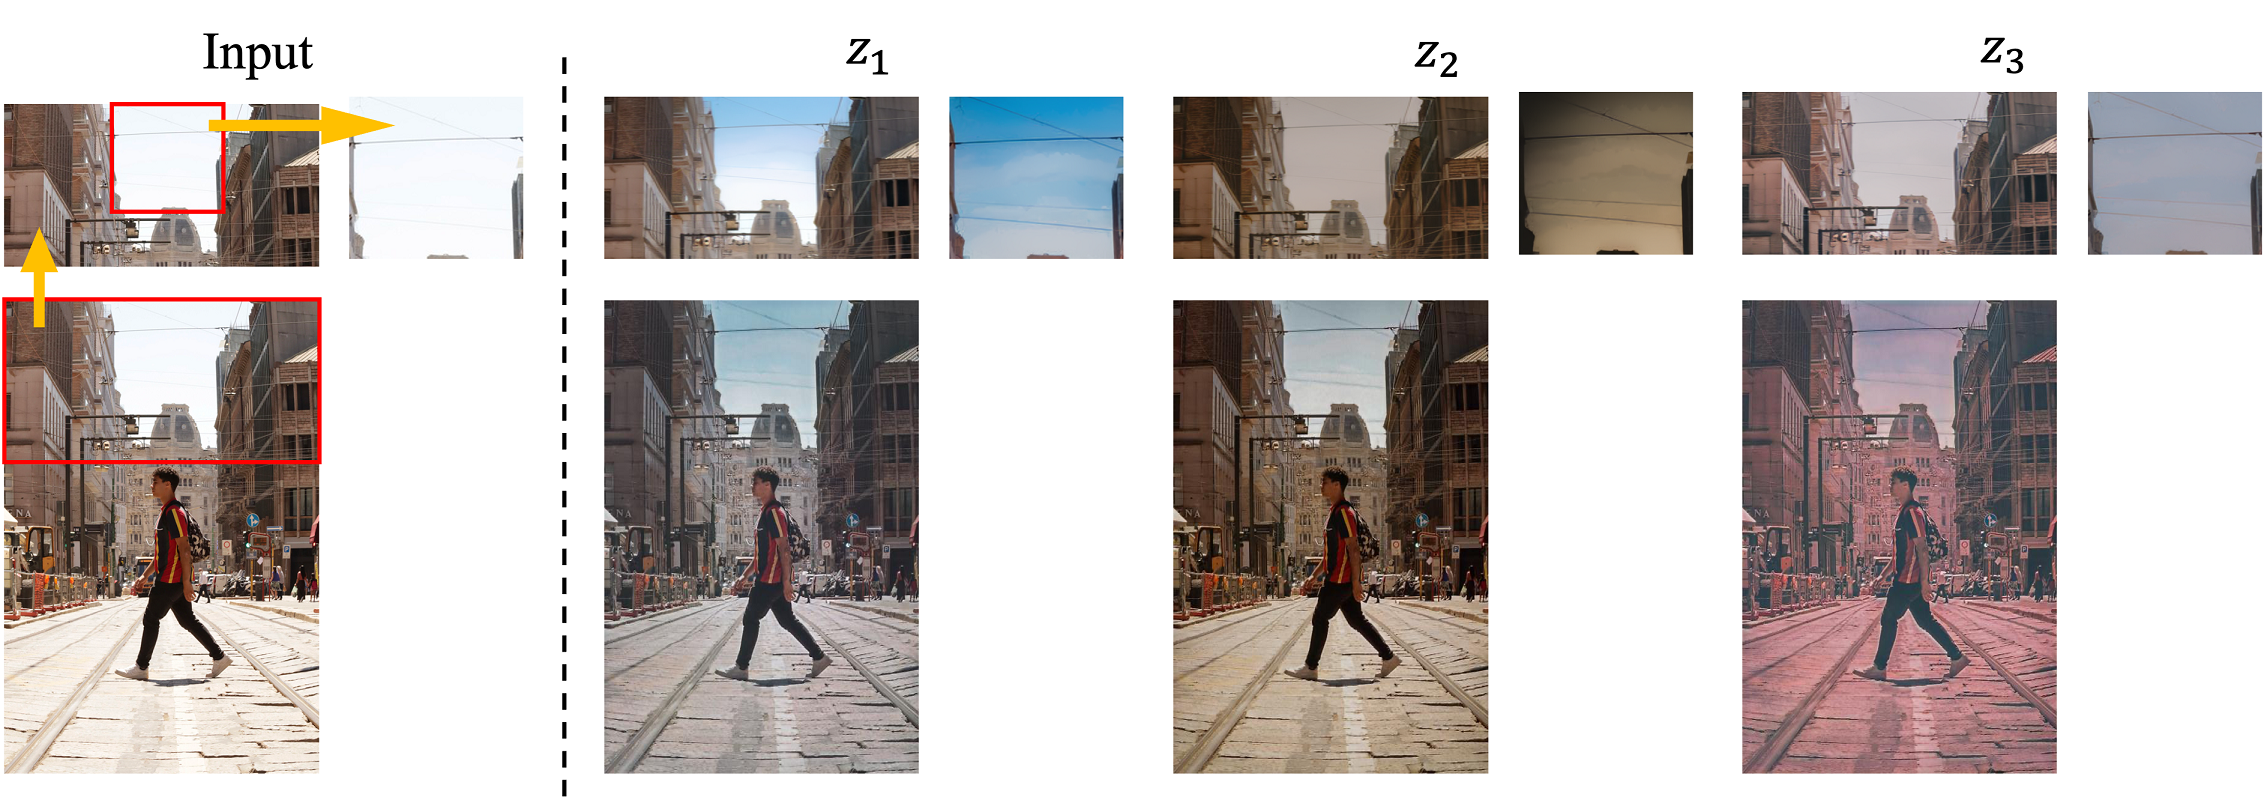
Edit the color tone of an image with the editing styles spatially adaptive to its content.
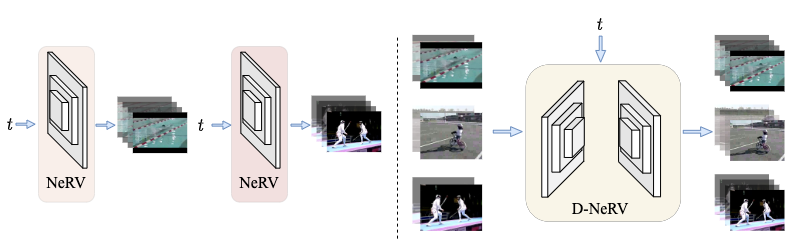
A video implicit neural representation that encodes large-scale and diverse videos faithfully and efficiently.
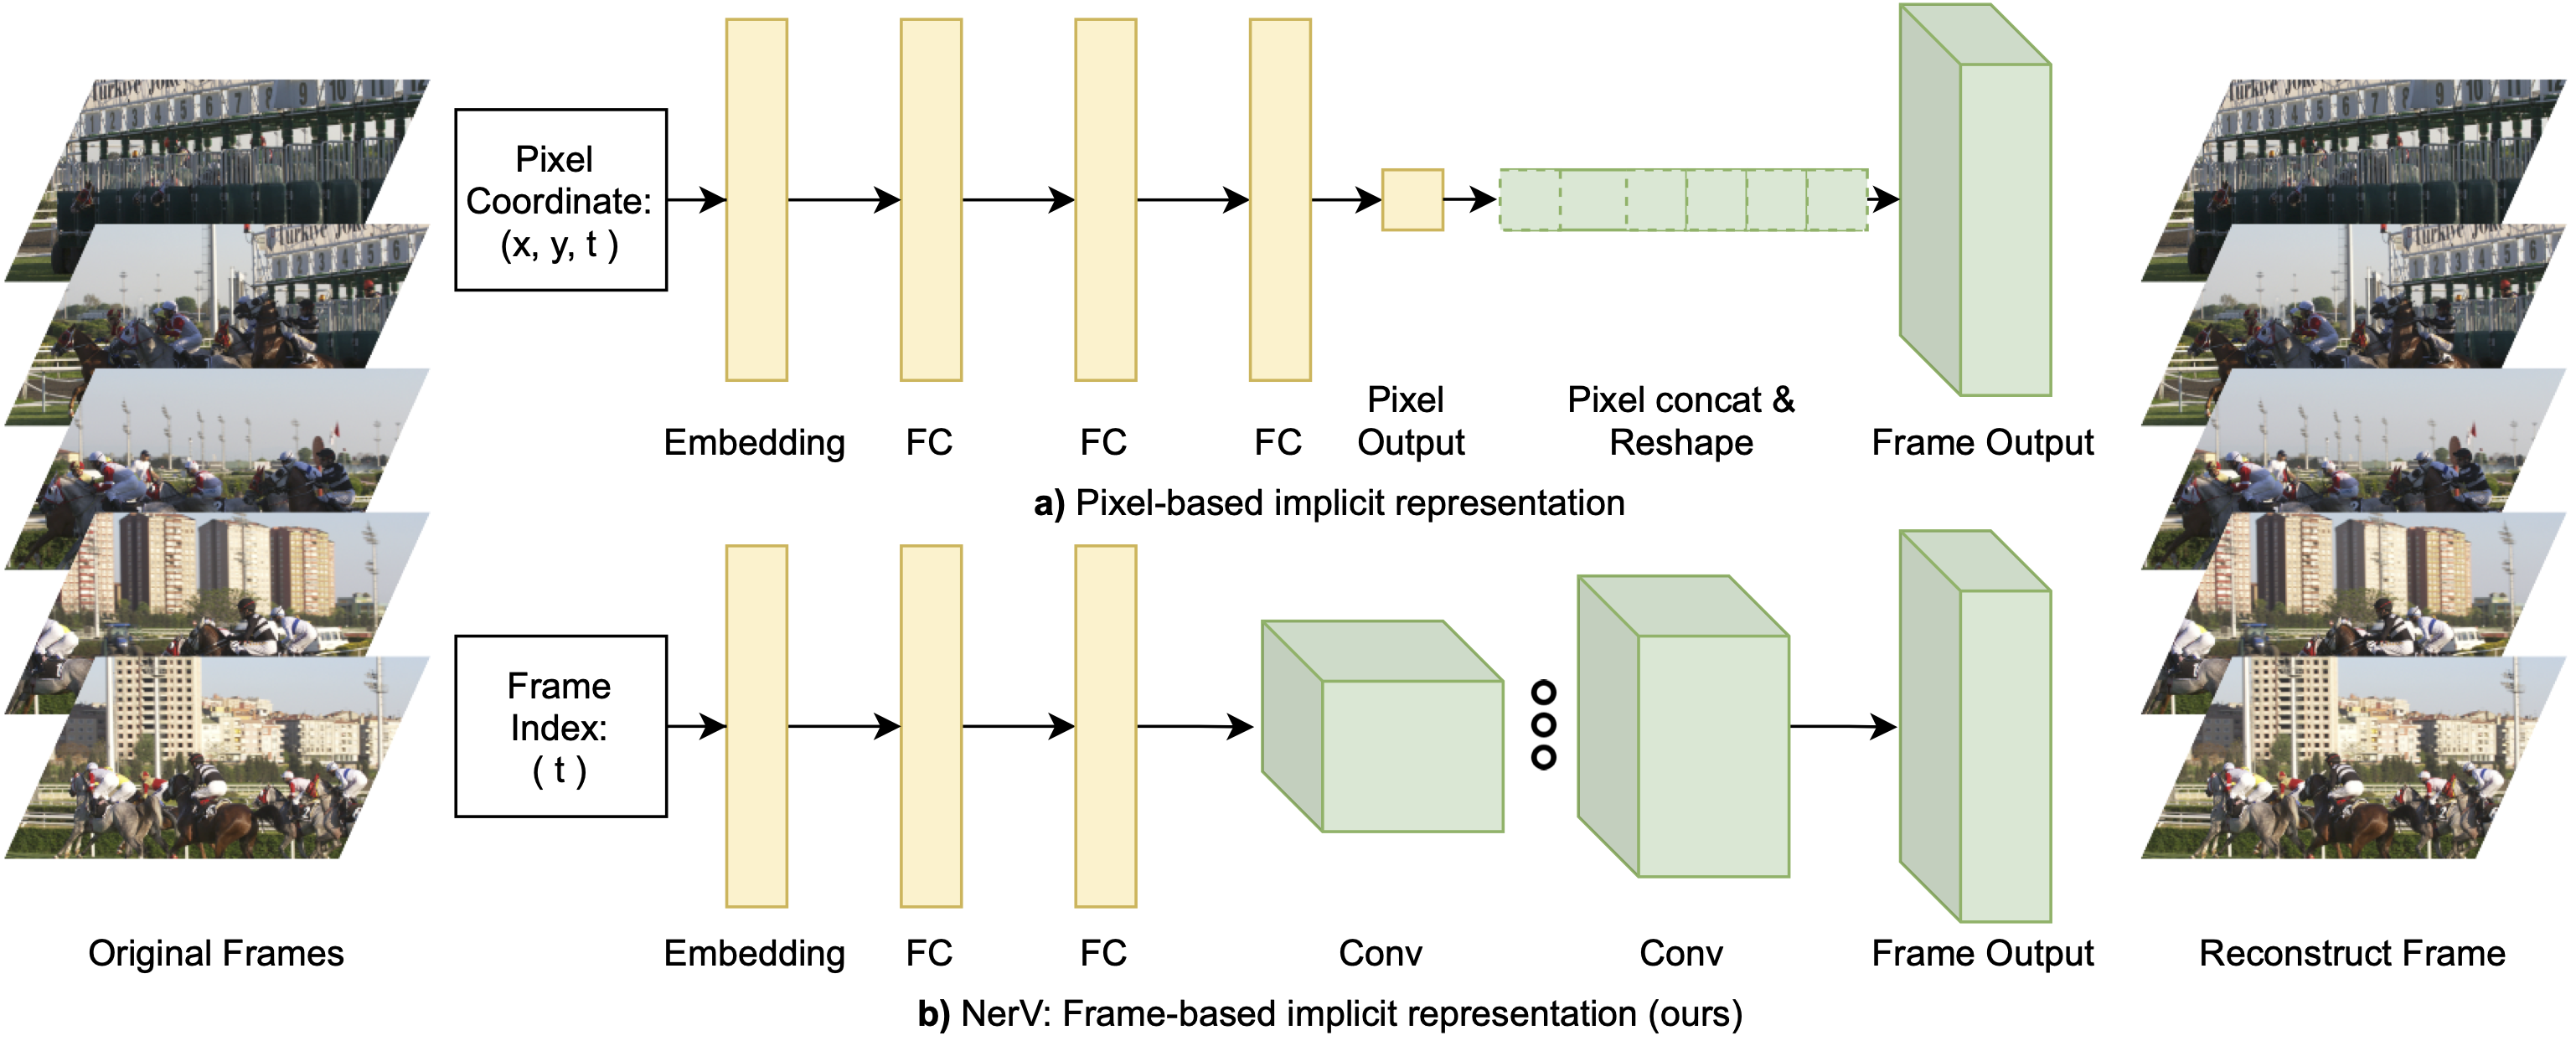
A frame-wise video implicit neural representation that encodes a video into a dedicated neural network's parameters
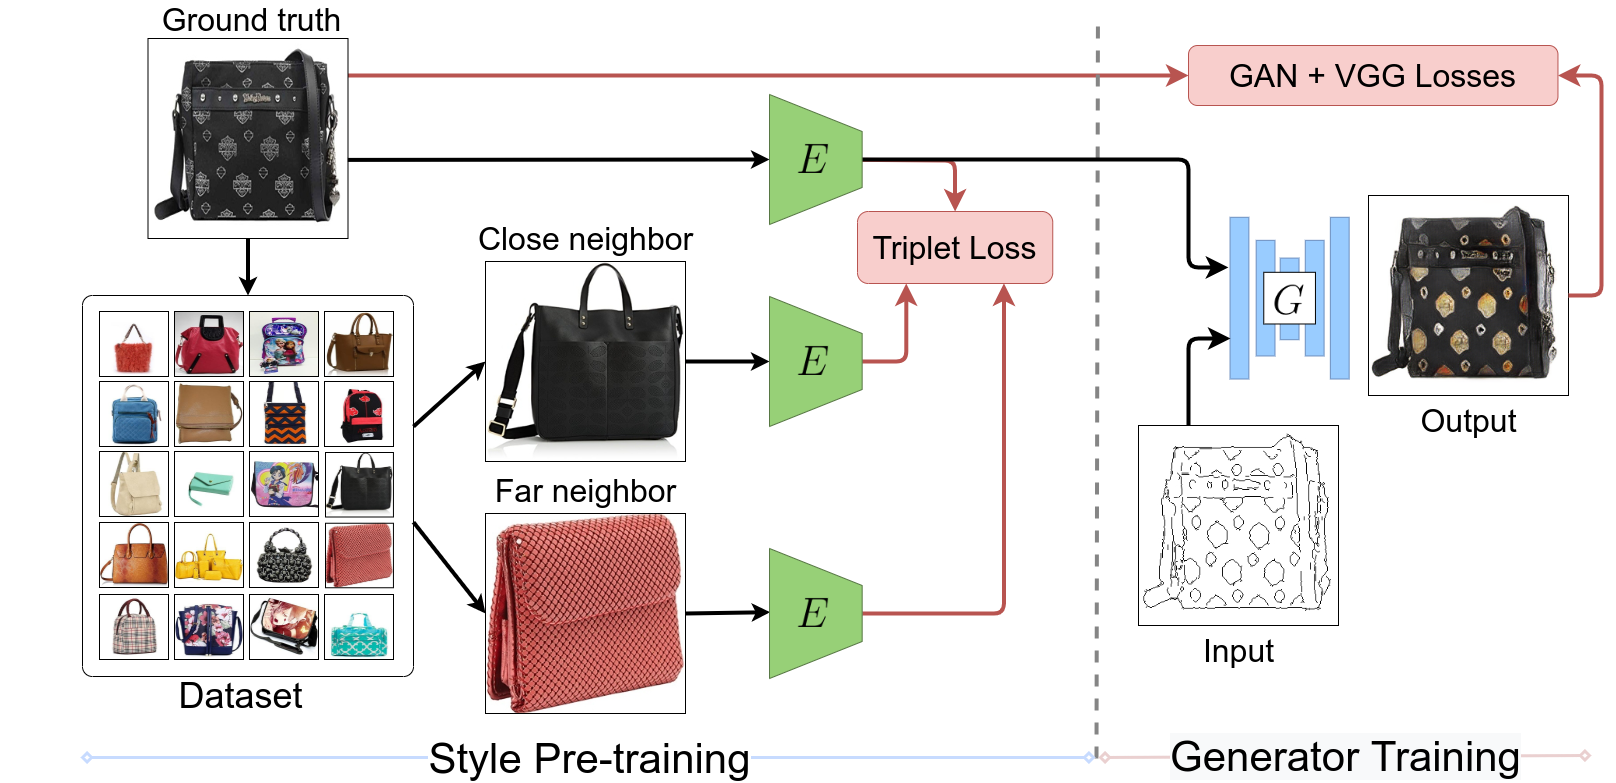
A two-stage MMI2I method via style encoder pre-training for simplifed losses and stablized training.
Services
- Reviewer: CVPR 2022, 2023, 2024, 2025‡, 2026, ICCV 2021, 2023, 2025, ECCV 2022, 2024‡, NeurIPS 2023, 2024, 2025, ICLR 2024, 2025, 2026, ICML 2024, 2025, 2026‡, AAAI 2024, 2025 ‡outstanding/silver reviewers
Generated by GPT-6 Astra